Publications

Recent Publications

Selected journal papers from the past three years are listed below. For a complete publication record, please visit Prof. Yun Zhang's homepage.

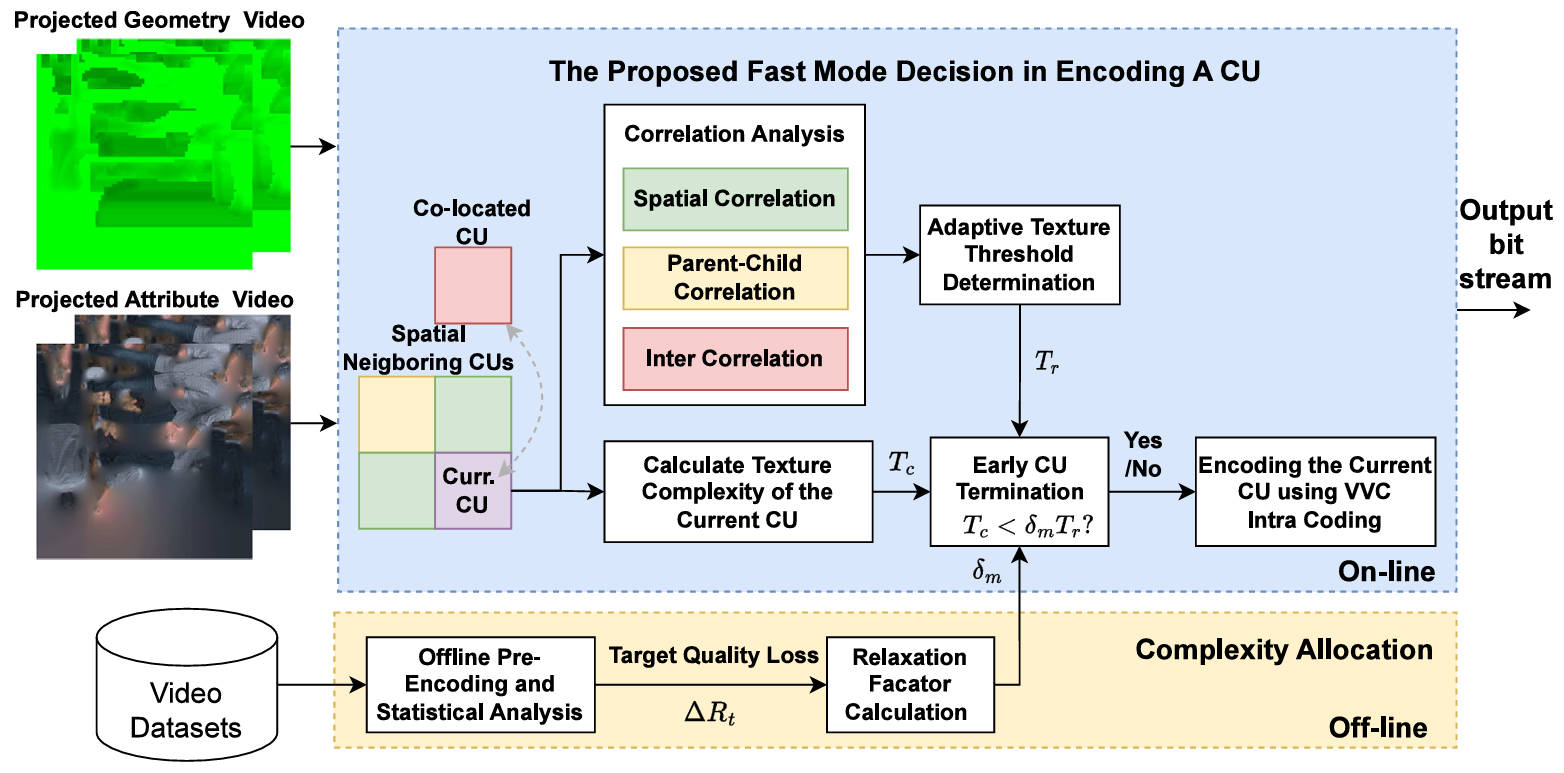
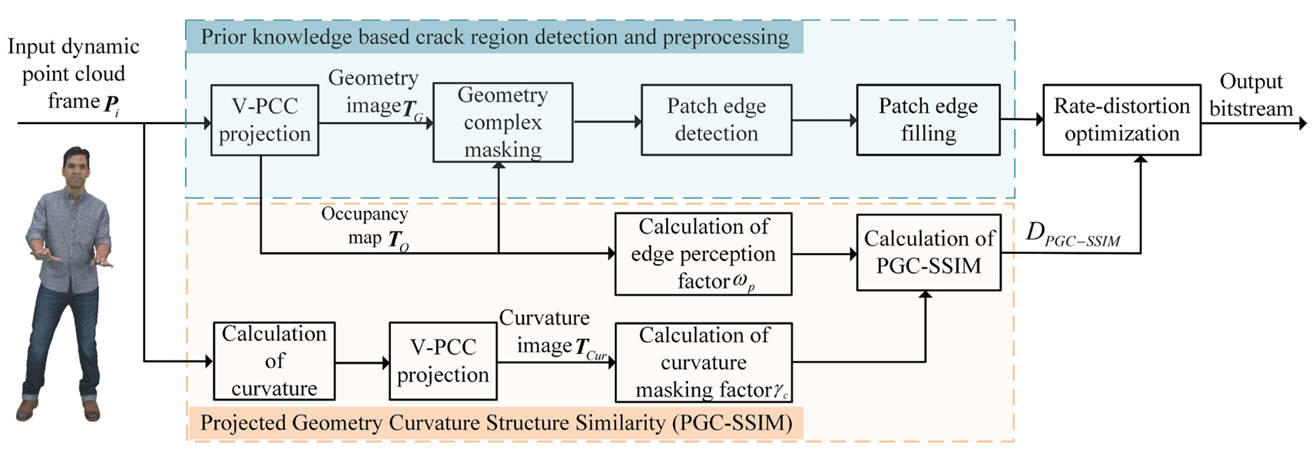
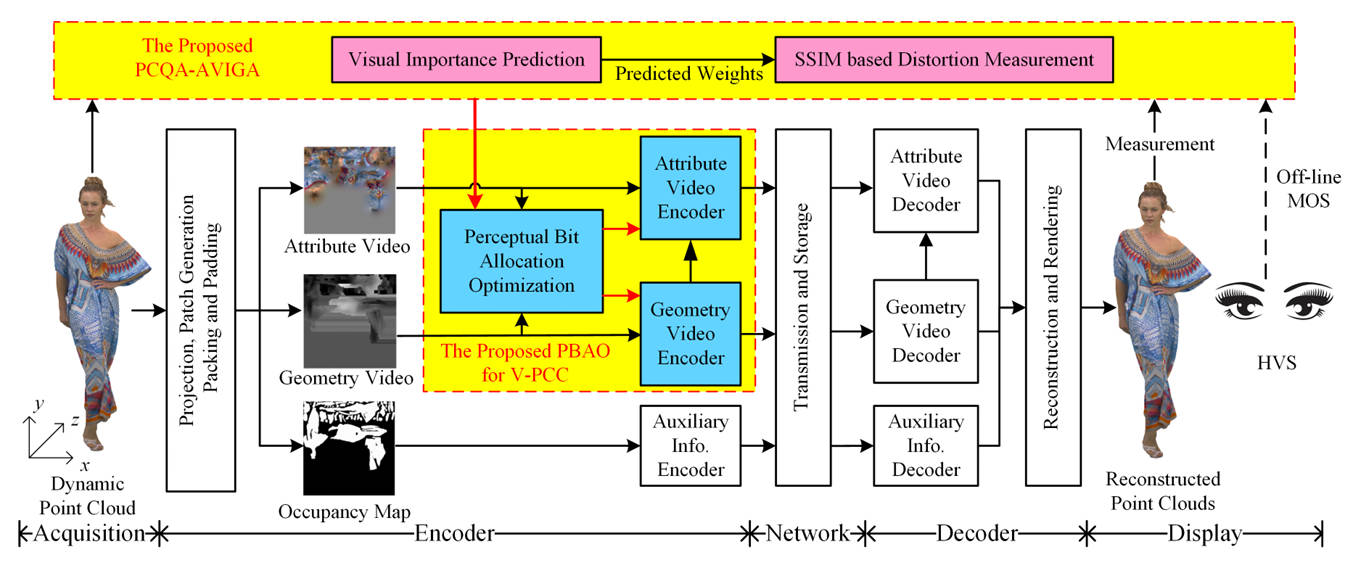
Representative figure for Perceptually Optimized Bit Allocation Between Attribute and Geometry for Video-Based Point Cloud Compression
Perceptually Optimized Bit Allocation Between Attribute and Geometry for Video-Based Point Cloud Compression

Yun Zhang, Lewen Fan, Mao Cui, Xiaoxia Huang, Sam Kwong. IEEE Transactions on Circuits and Systems for Video Technology, 2026.

Summary: To account for the content-dependent perceptual importance of geometry and attributes in V-PCC, the work introduces PCQA-AVIGA and derives 2D/3D perceptual distortion and rate models. Two PBAO schemes then adapt geometry and attribute quantization under a total-rate constraint, reducing BDBR by 6.44% on average while improving perceptual quality.
papercodeprojectdigest
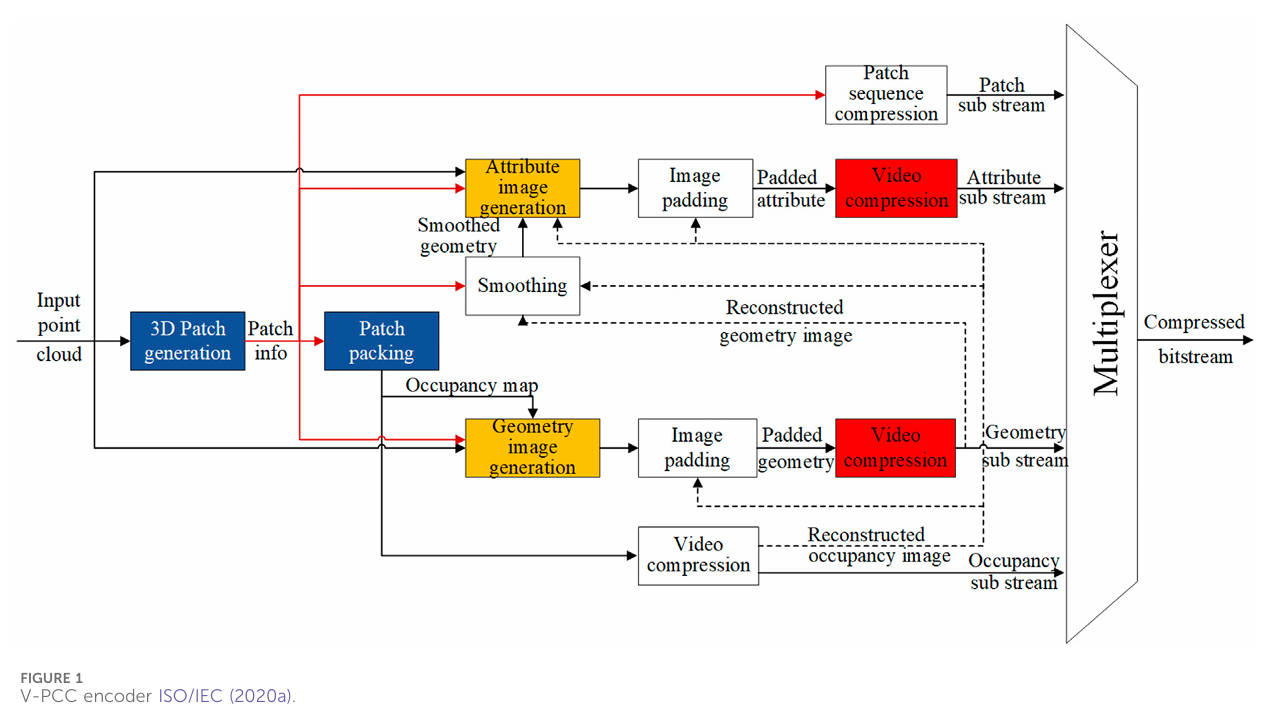
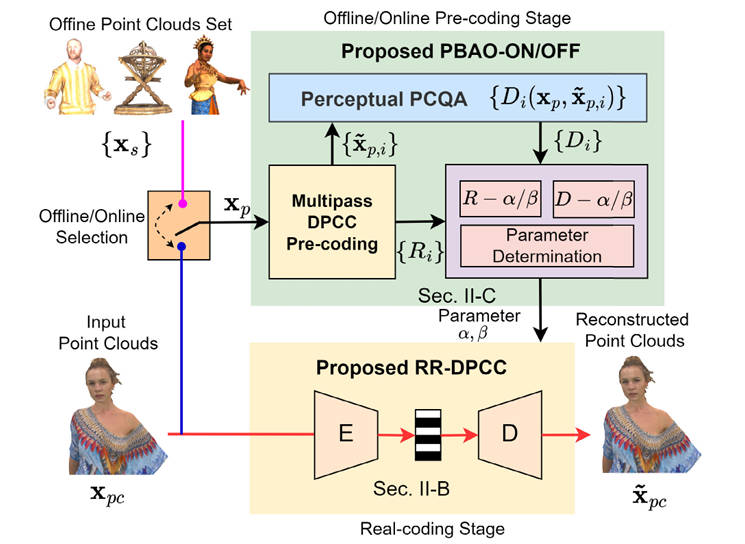
Representative figure for Rate-Reconfigurable Deep Point Cloud Compression With Perceptual Bit Allocation Optimization
Rate-Reconfigurable Deep Point Cloud Compression With Perceptual Bit Allocation Optimization

Yun Zhang, Lewen Fan, Zixi Guo, Xu Wang, Xiaoxia Huang, Sam Kwong. IEEE Transactions on Image Processing, vol. 35, pp. 3451-3465, 2026.

Summary: RR-DPCC addresses the need to train separate models for different target rates by introducing a rate-reconfigurable codec with online and offline perceptual bit allocation. A single model supports flexible rate control while balancing geometry and attribute coding costs.

papercodeprojectdigest
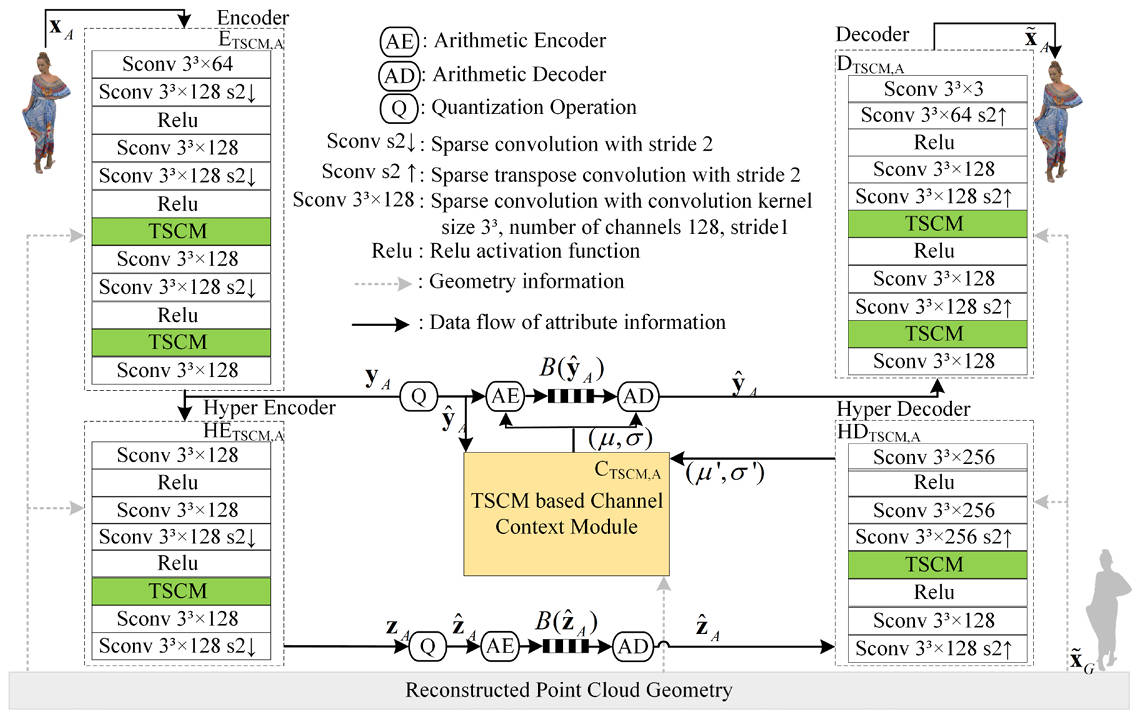
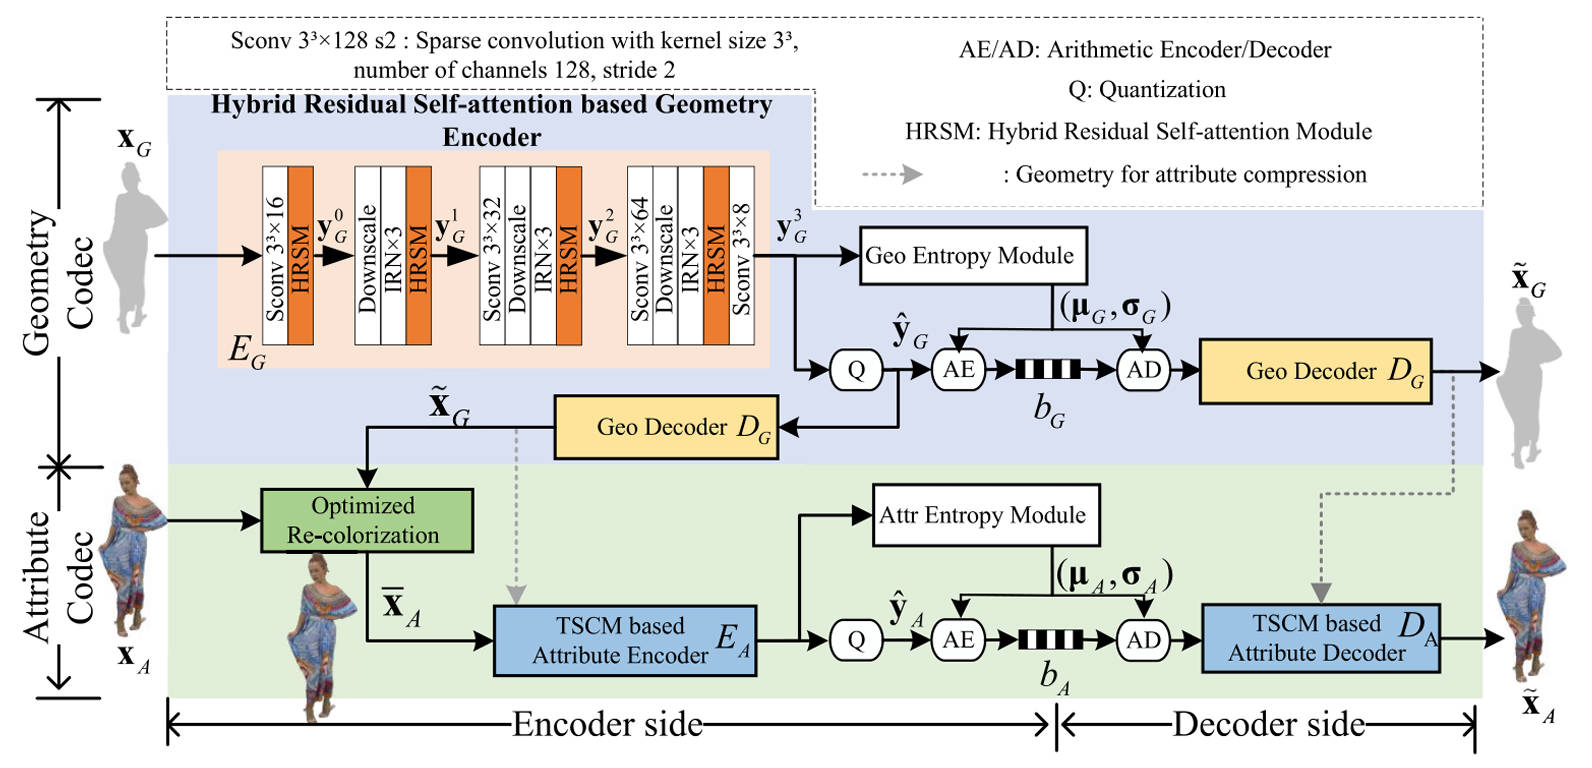
Representative figure for Deep-JGAC: End-to-End Deep Joint Geometry and Attribute Compression for Dense Colored Point Clouds
Deep-JGAC: End-to-End Deep Joint Geometry and Attribute Compression for Dense Colored Point Clouds

Yun Zhang, Zhiwei Guo, Zixi Guo, Linwei Zhu, C.-C. Jay Kuo. IEEE Transactions on Circuits and Systems for Video Technology, 2026.

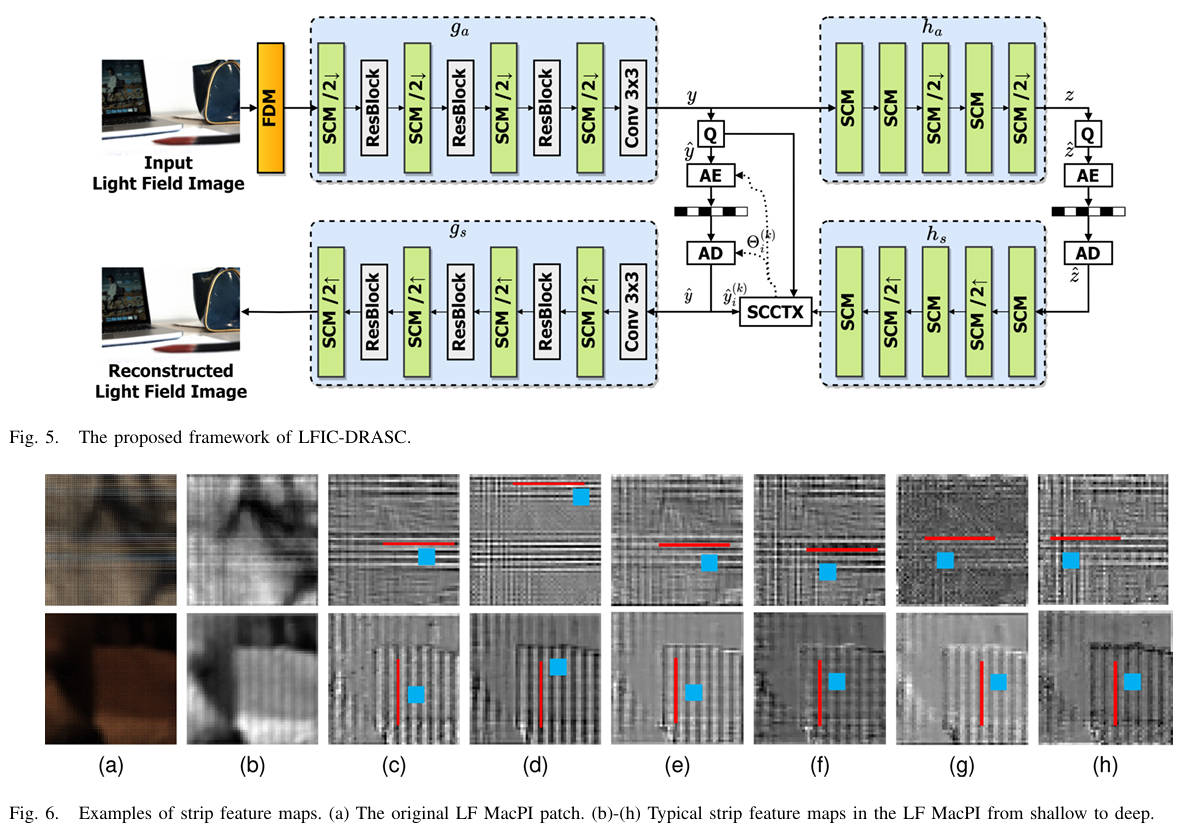
Summary: Deep-JGAC provides end-to-end joint geometry and attribute compression for dense colored point clouds. Residual self-attention geometry coding, re-colorization, and joint entropy modeling improve the coordinated representation and coding efficiency of both components.

papercodeprojectdigest
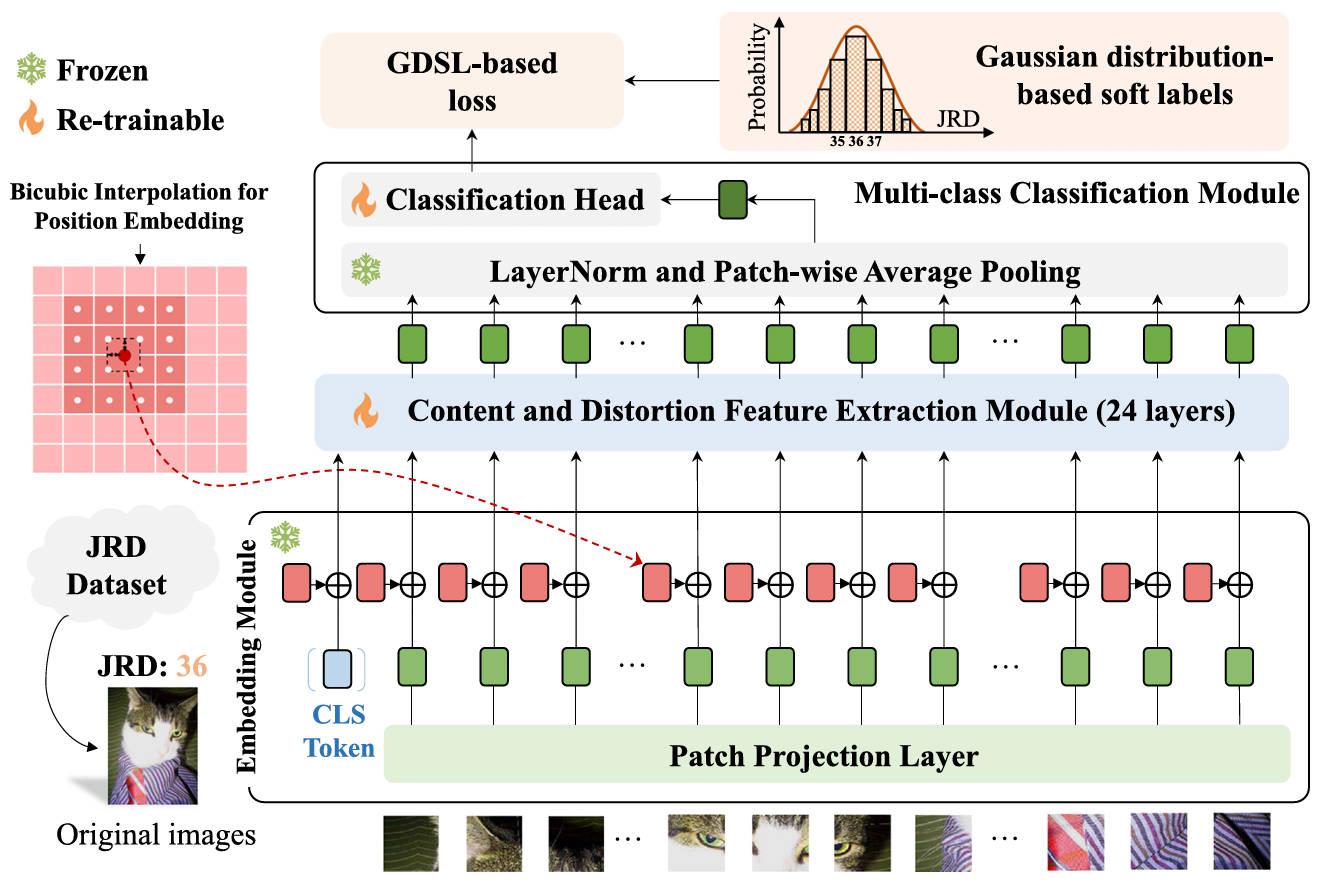
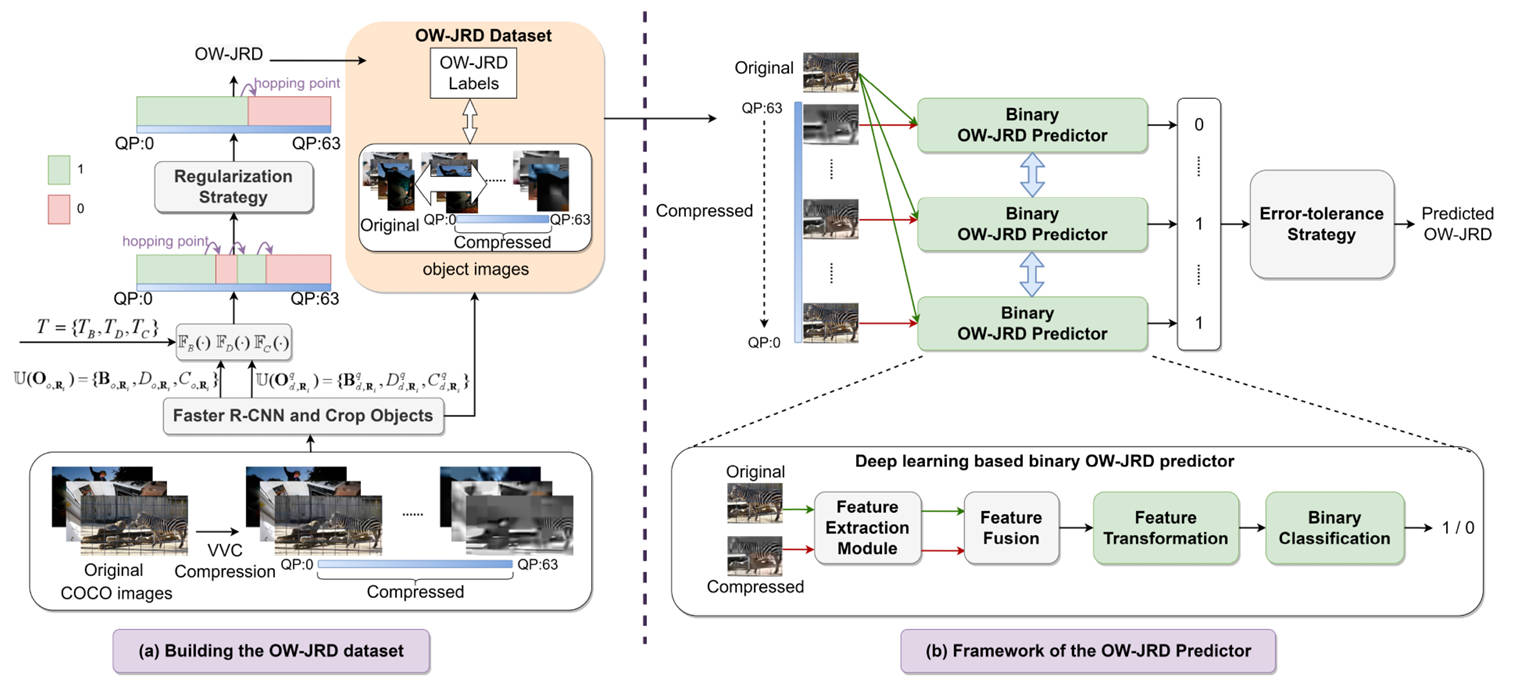
Representative figure for DT-JRD: Deep Transformer based Just Recognizable Difference Prediction Model for Video Coding for Machines
DT-JRD: Deep Transformer based Just Recognizable Difference Prediction Model for Video Coding for Machines

Junqi Liu, Yun Zhang, Xiaoqi Wang, Long Xu, Sam Kwong. IEEE Transactions on Multimedia, vol. 28, pp. 114-127, 2026.

Summary: The work defines JRD as the smallest difference recognizable by machine vision and formulates its prediction as multi-class classification. A Transformer jointly models content and distortion so the codec can remove unnecessary bits while preserving downstream analysis accuracy.

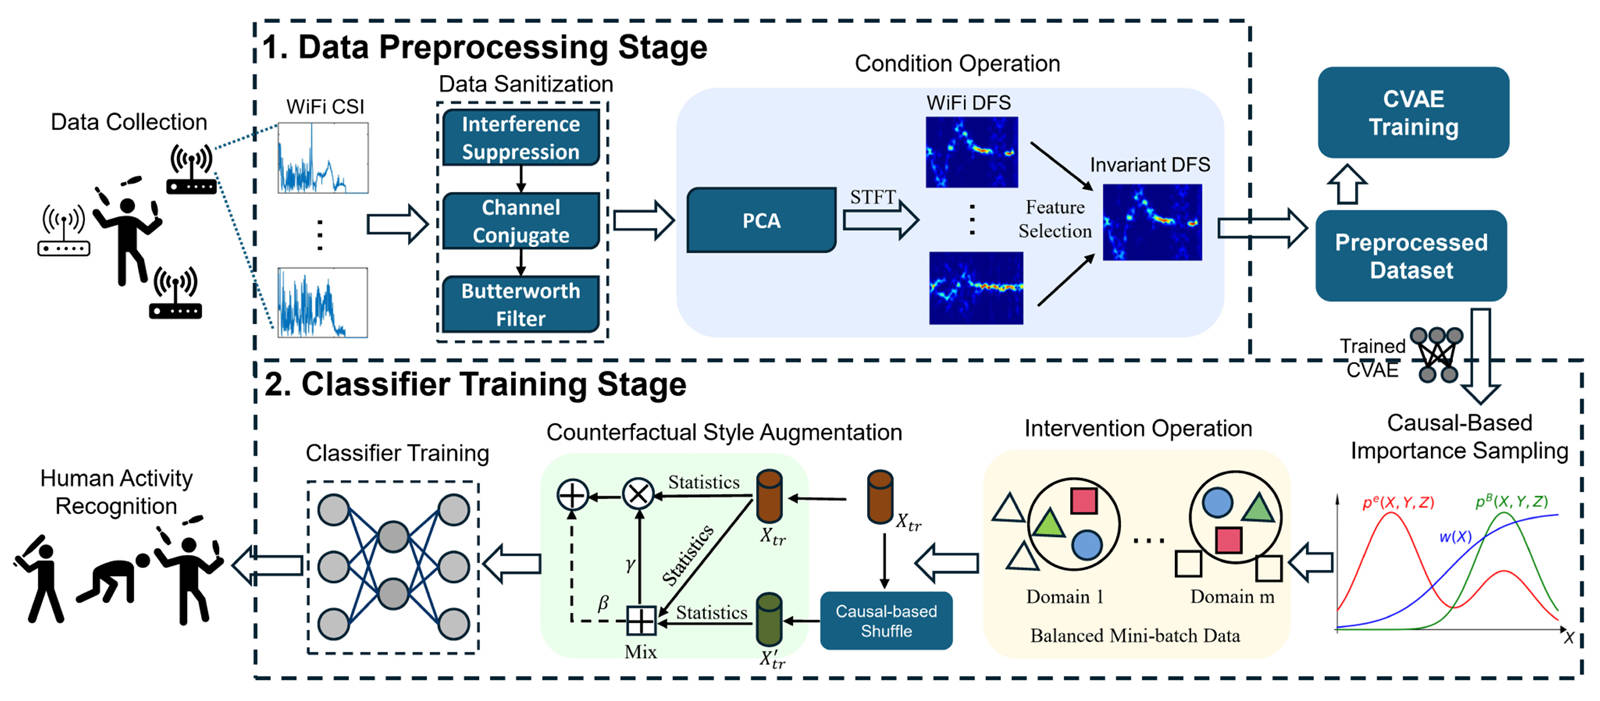
Representative figure for CausalFi: Causality-Based Cross-Domain Human Activity Recognition With Wi-Fi
CausalFi: Causality-Based Cross-Domain Human Activity Recognition With Wi-Fi

Yinan Chen, Yang Zhou, Xiaoxia Huang, Yun Zhang, Yuguang Fang. IEEE Transactions on Networking, vol. 34, pp. 4959-4973, 2026.

Summary: CausalFi addresses latent confounding and domain shifts in cross-domain Wi-Fi CSI-based human activity recognition. Its structural causal model combines causal feature selection, importance sampling, and counterfactual style augmentation to isolate stable action-related features, achieving 92.6% average accuracy across realistic domains and commercial Wi-Fi devices.

papercodeprojectdigest
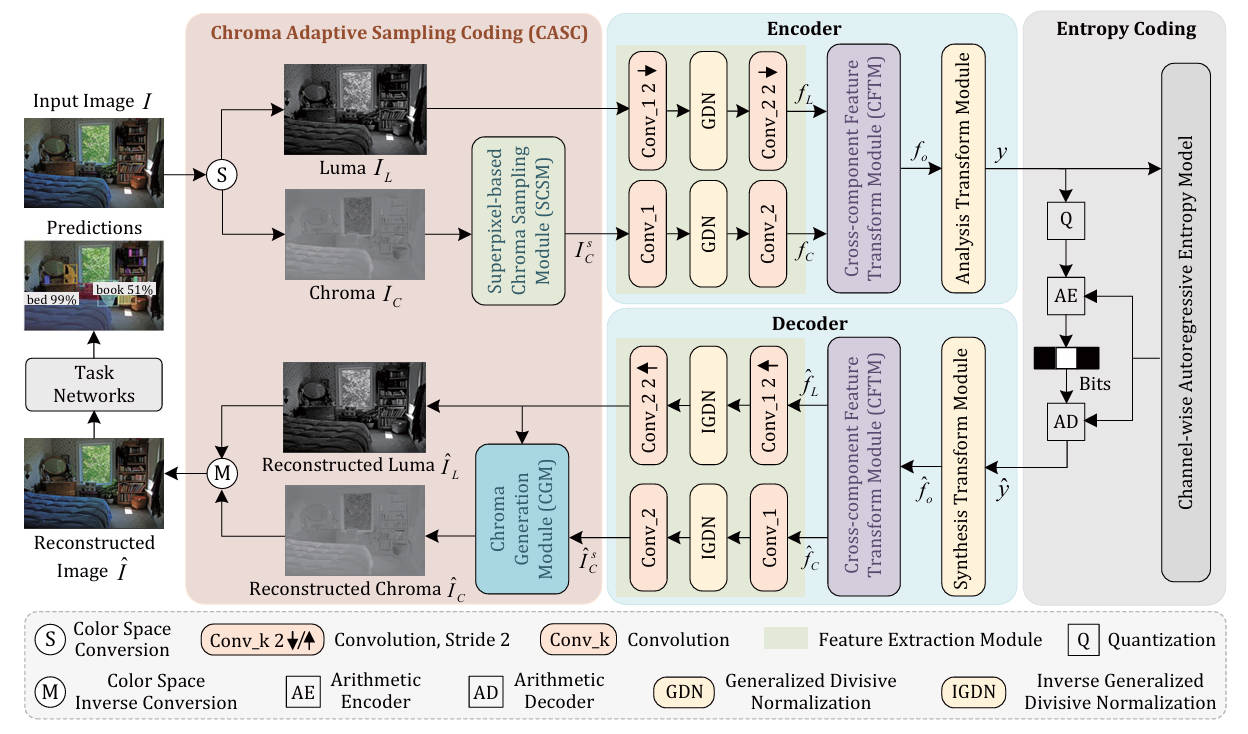
Representative figure for CA-LIC: Chroma-Aware Learned Image Compression for Machines
CA-LIC: Chroma-Aware Learned Image Compression for Machines

Renyi Chen, Liqian Zhang, Yun Zhang, Li Li, Fu Lee Wang, Zhaoqing Pan. IEEE Transactions on Multimedia, 2026.

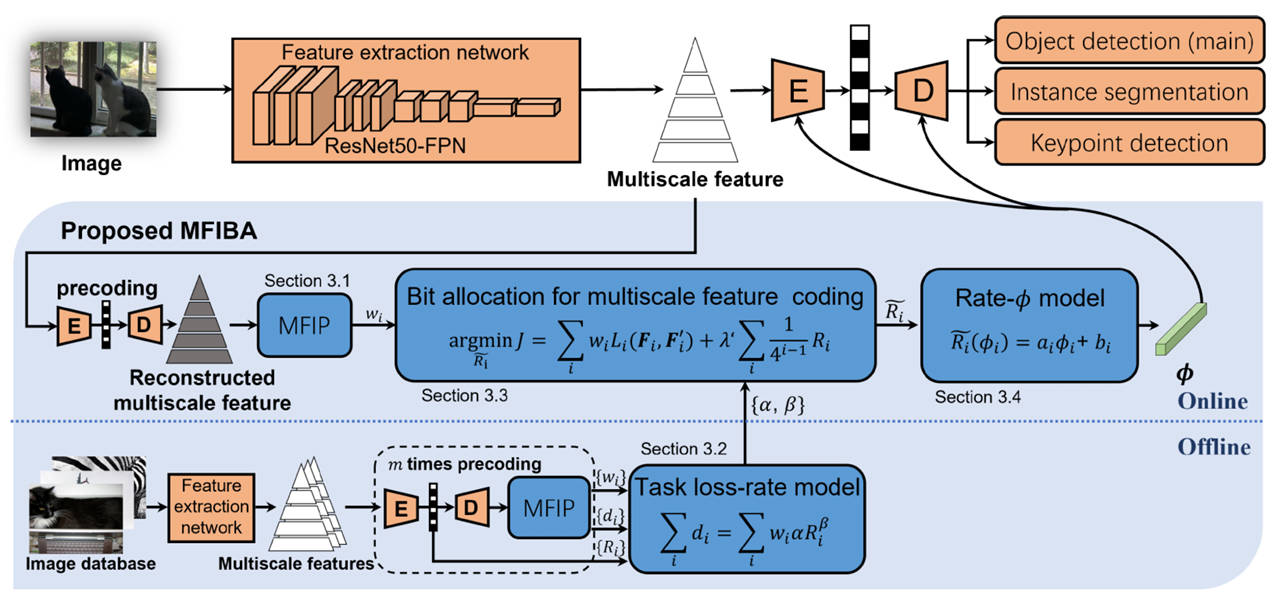
Summary: CA-LIC differentiates luma and chroma coding according to their asymmetric importance to downstream machine-vision tasks. CASC reduces chroma volume through superpixel-level semantic aggregation and restores it with luma-guided compensation, while CFTM suppresses cross-component redundancy; the framework improves rate-task performance in object detection, instance segmentation, and semantic segmentation.

papercodeprojectdigest
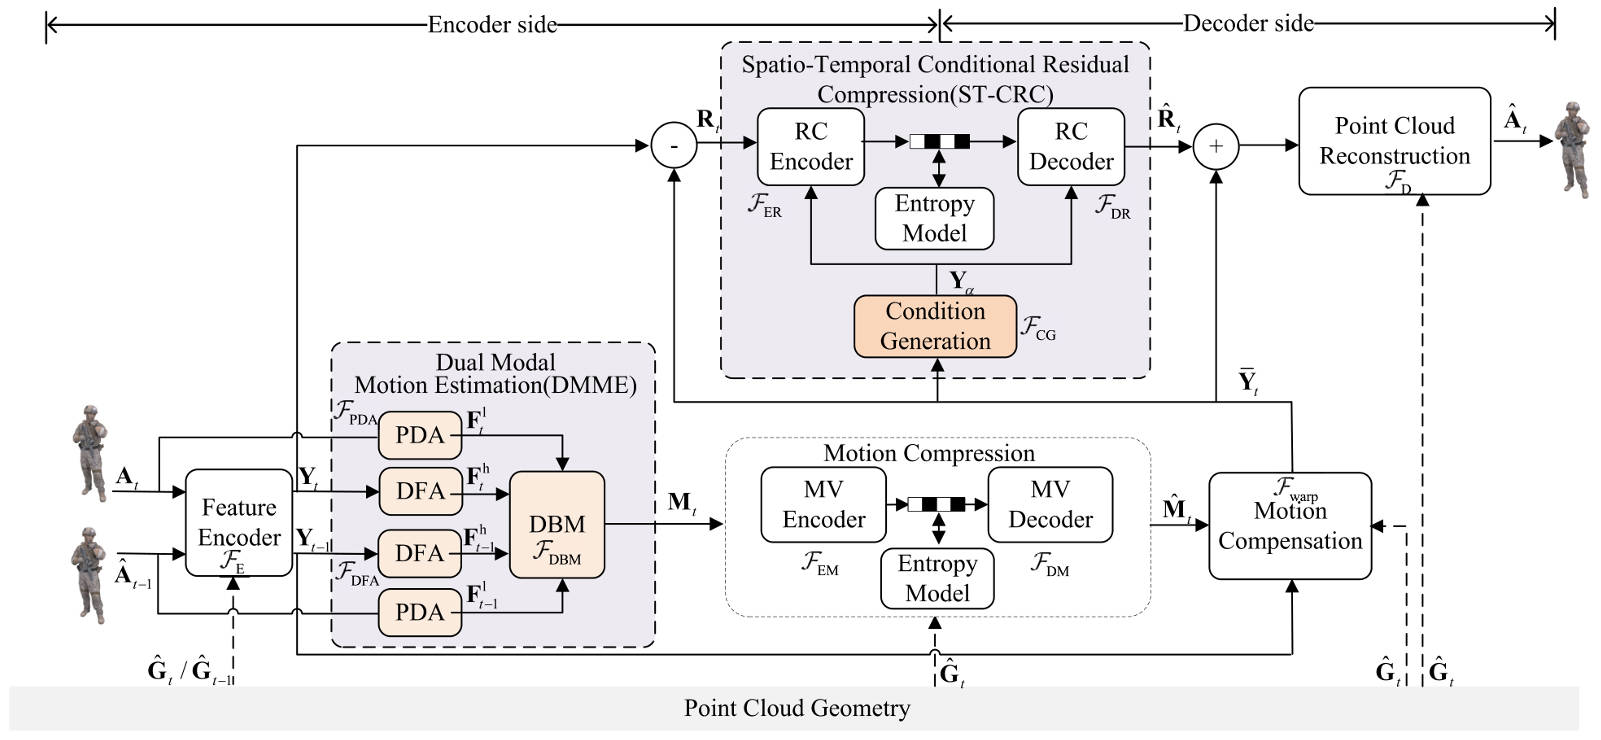
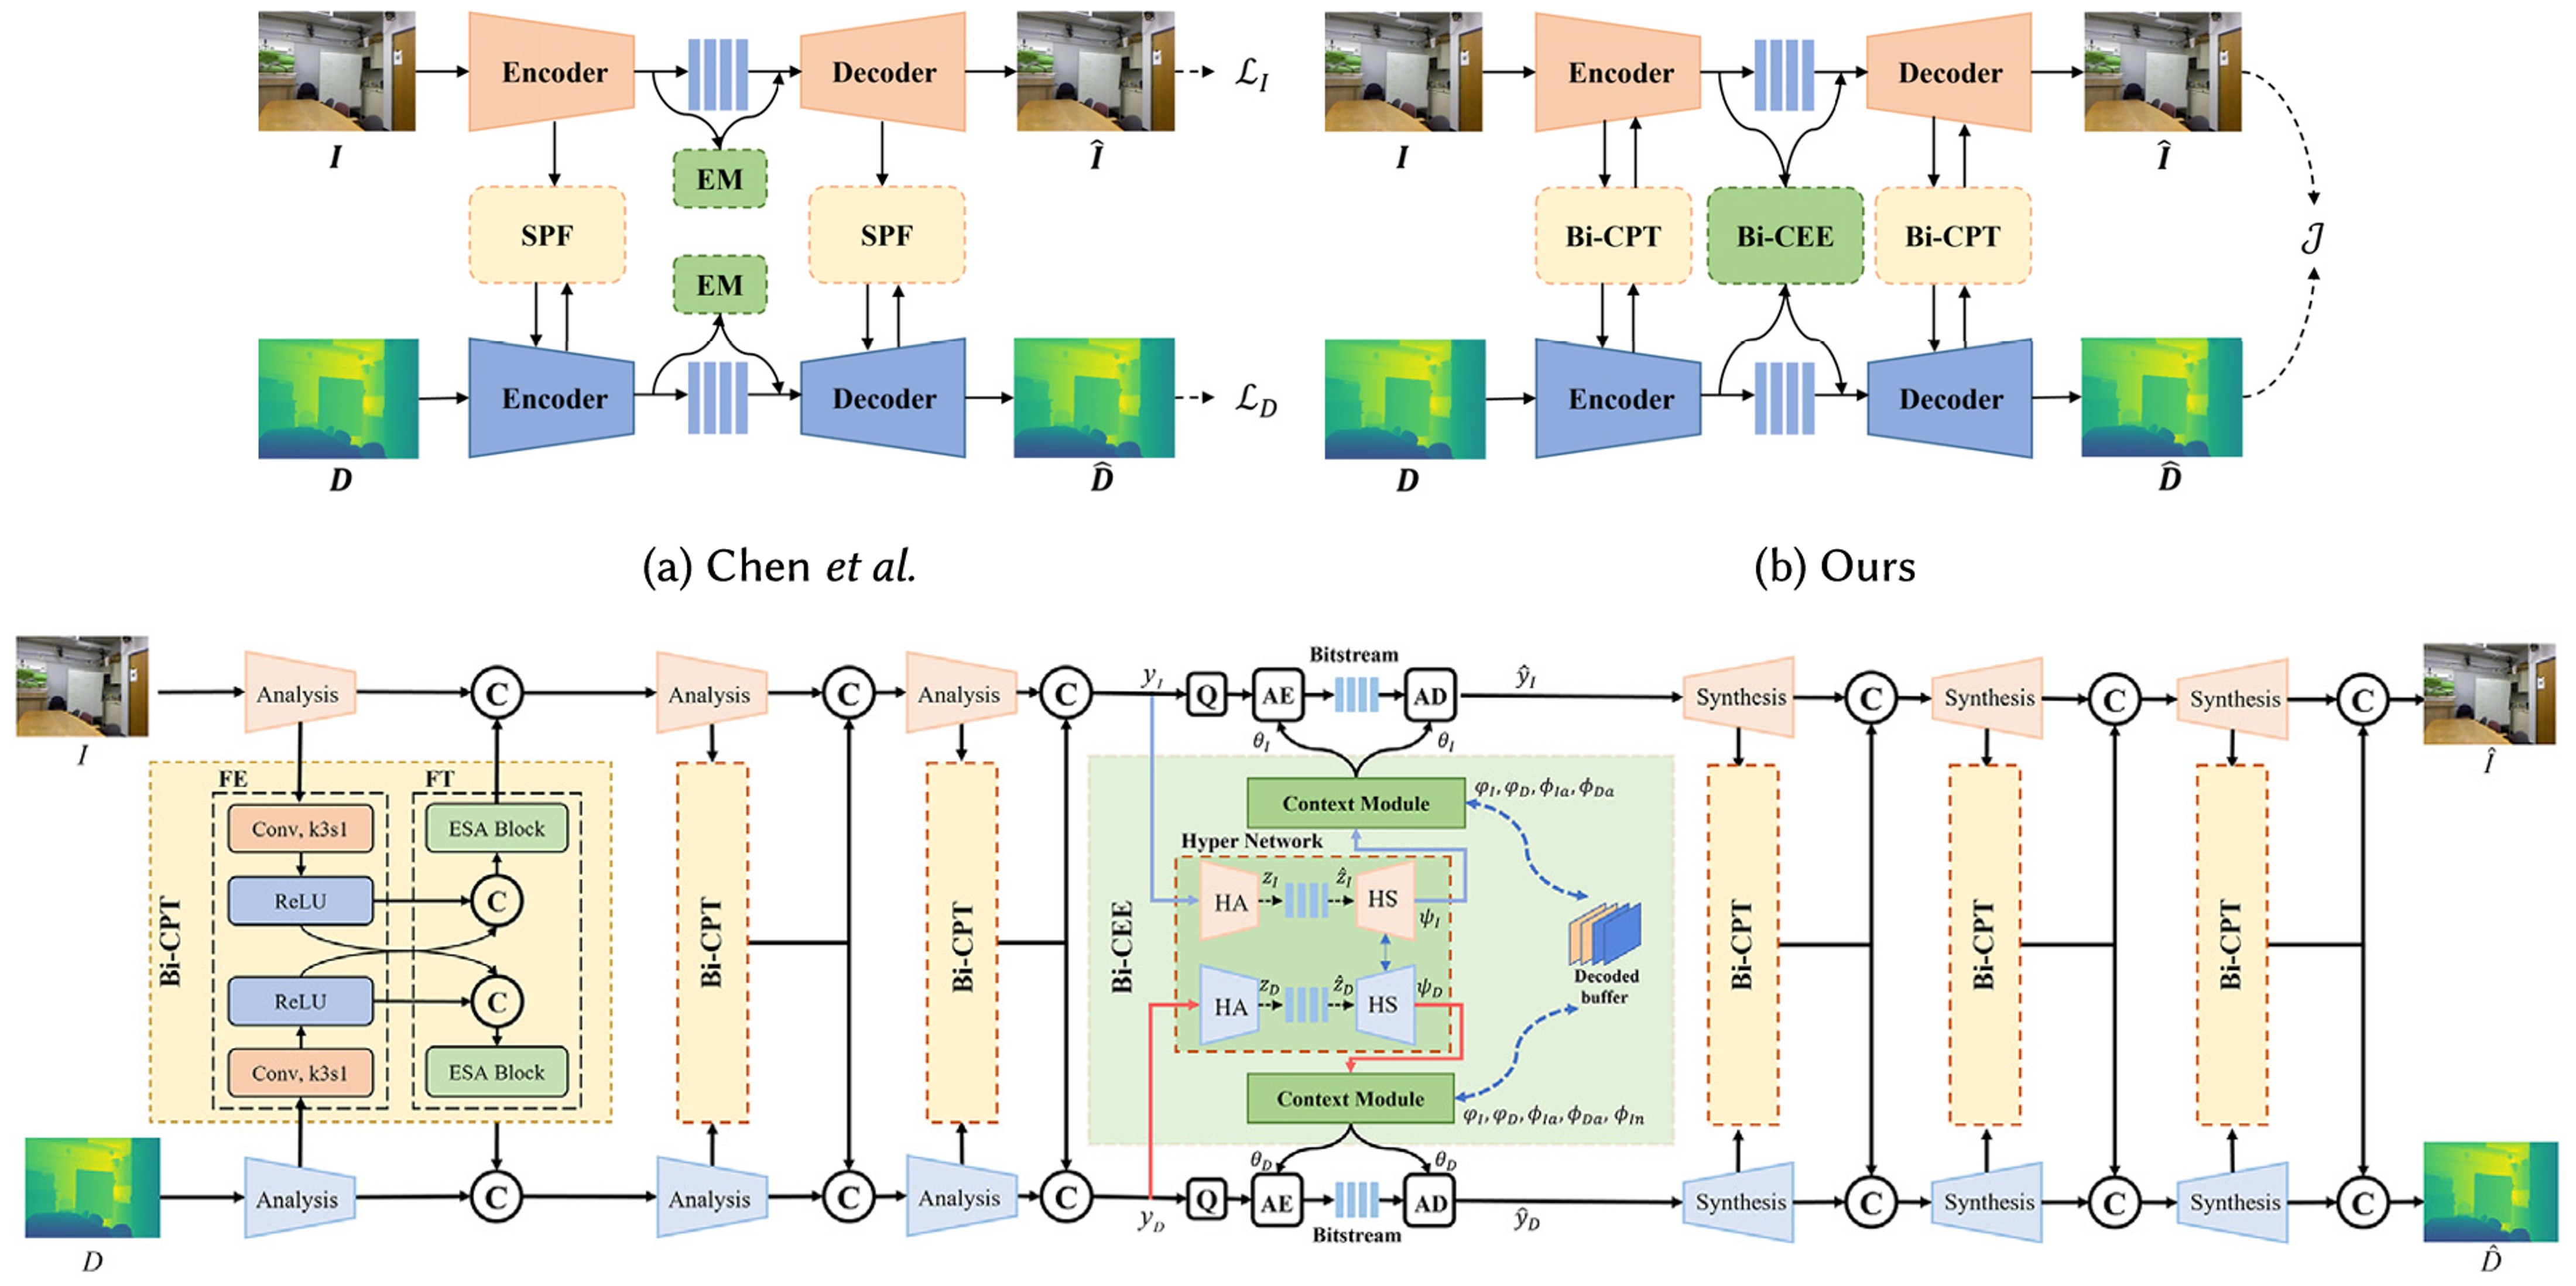
Representative figure for Deep Dynamic Point Cloud Attribute Compression Using Dual-Modal Motion Estimation and Spatio-Temporal Conditional Residual Coding
Deep Dynamic Point Cloud Attribute Compression Using Dual-Modal Motion Estimation and Spatio-Temporal Conditional Residual Coding

Zhiwei Guo, Yun Zhang, Linwei Zhu. IEEE Transactions on Broadcasting, vol. 72, no. 3, pp. 877-889, 2026.

Summary: DD-PCAC unifies motion estimation, compensation, and residual coding in an end-to-end differentiable framework for dynamic point cloud attributes. DMME combines dynamic ball matching with pixel- and feature-domain aggregation, while ST-CRC exploits spatiotemporal conditions for residual coding, reducing average bit rate by 31.57% and 30.33% over TSC-PCAC and G-PCC, respectively.

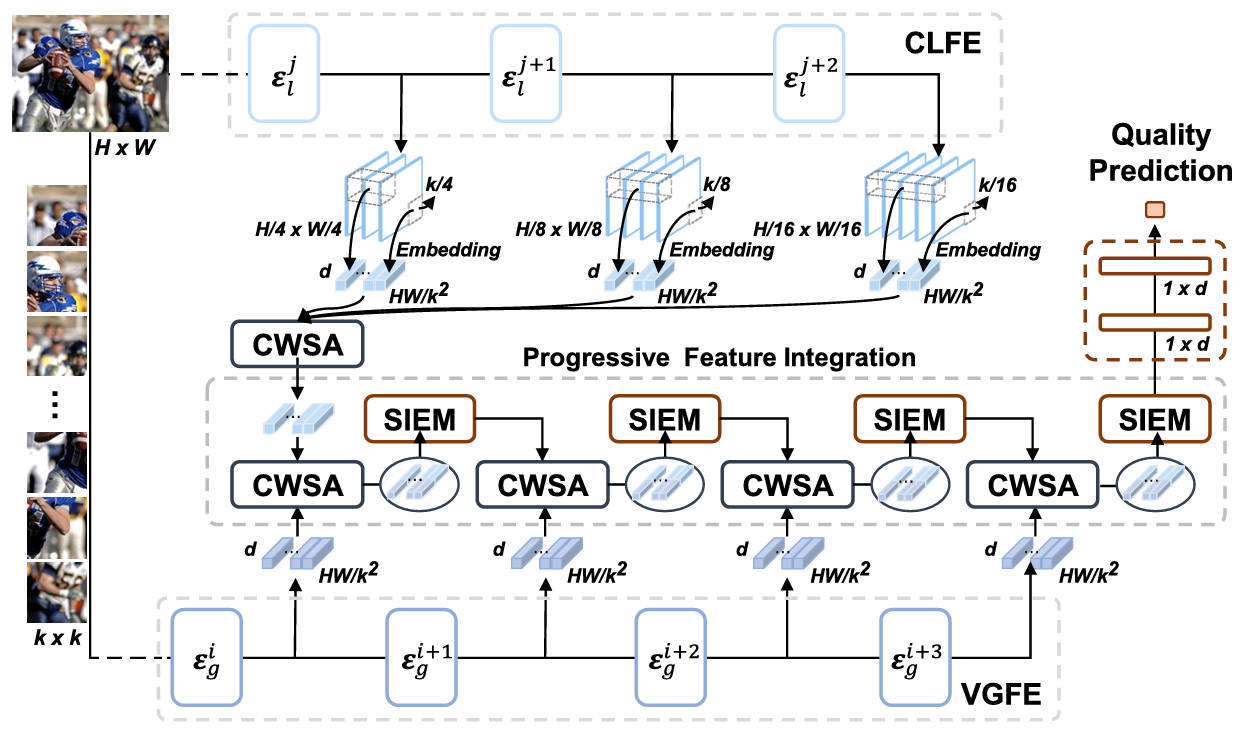
Representative figure for Global–Local Progressive Integration and Semantic-Aligned Quality Transfer for No-Reference Image Quality Assessment
Global–Local Progressive Integration and Semantic-Aligned Quality Transfer for No-Reference Image Quality Assessment

Xiaoqi Wang, Yun Zhang. ACM Transactions on Multimedia Computing, Communications and Applications, 2026.

Summary: GlintIQA combines ViT-derived global context with CNN-based fine-grained local distortion features and progressively fuses them through channel self-attention and spatial interaction. Its SAQT strategy transfers subjective scores between semantically similar images with identical distortions to build a large-scale training set, substantially improving cross-dataset generalization.

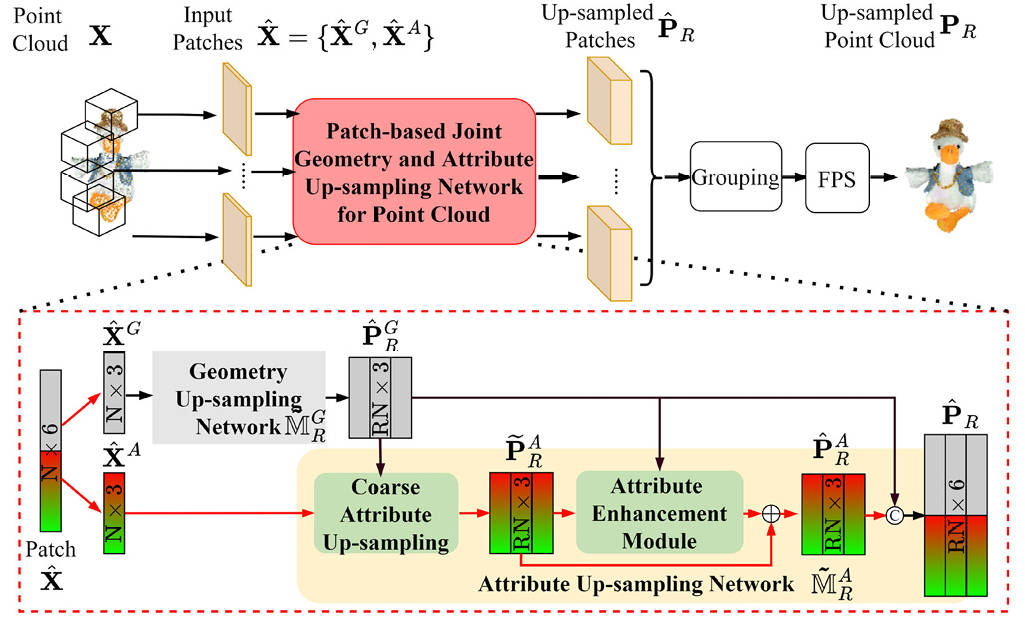
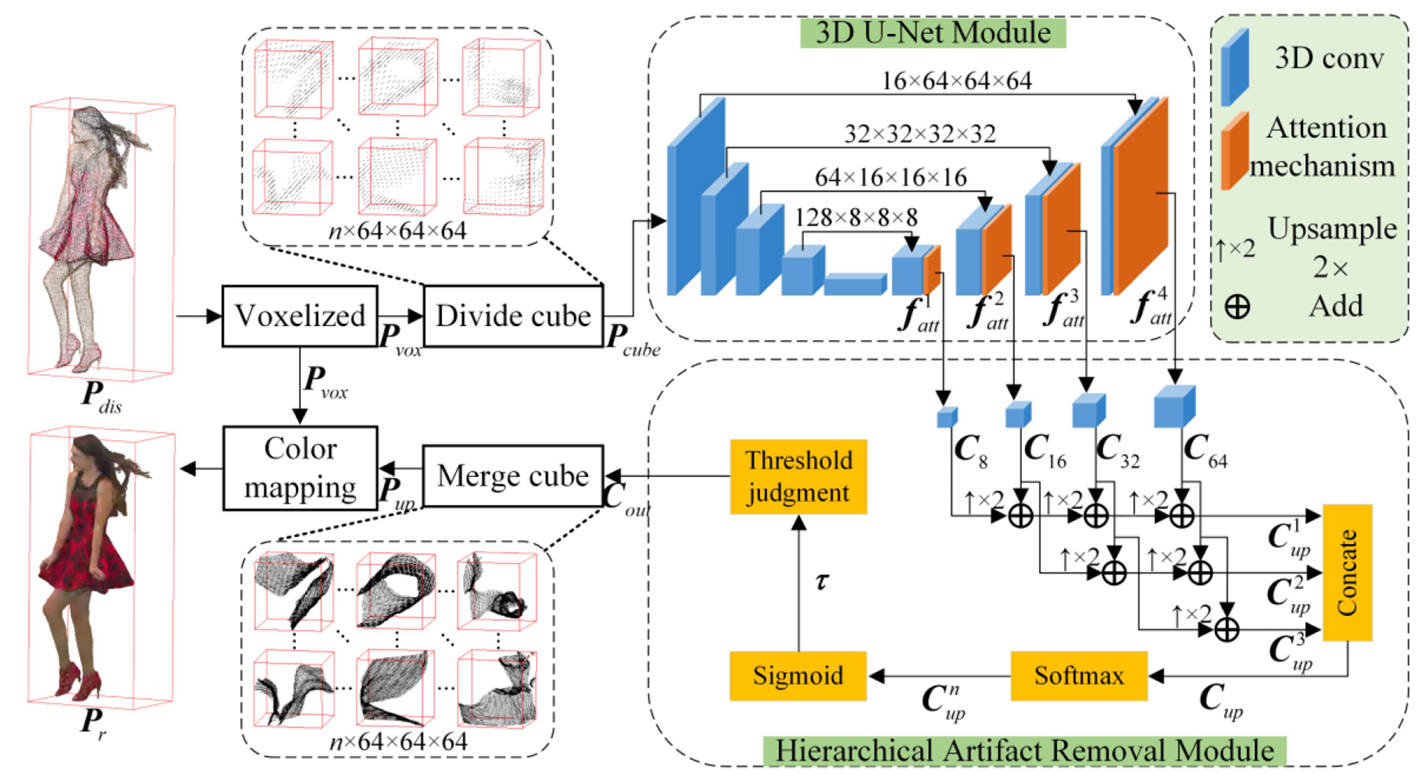
Representative figure for Deep Learning based Joint Geometry and Attribute Upsampling for Large-Scale Colored Point Clouds
Deep Learning based Joint Geometry and Attribute Upsampling for Large-Scale Colored Point Clouds

Yun Zhang, Feifan Chen, Na Li, Xu Wang, Fen Miao, Sam Kwong. IEEE Transactions on Image Processing, vol. 35, pp. 1305-1320, 2026.

Summary: JGAU jointly upsamples point cloud geometry and attributes by exploiting their spatial correlation. The study also establishes a large-scale colored point cloud upsampling dataset to support training and evaluation at multiple enlargement factors.

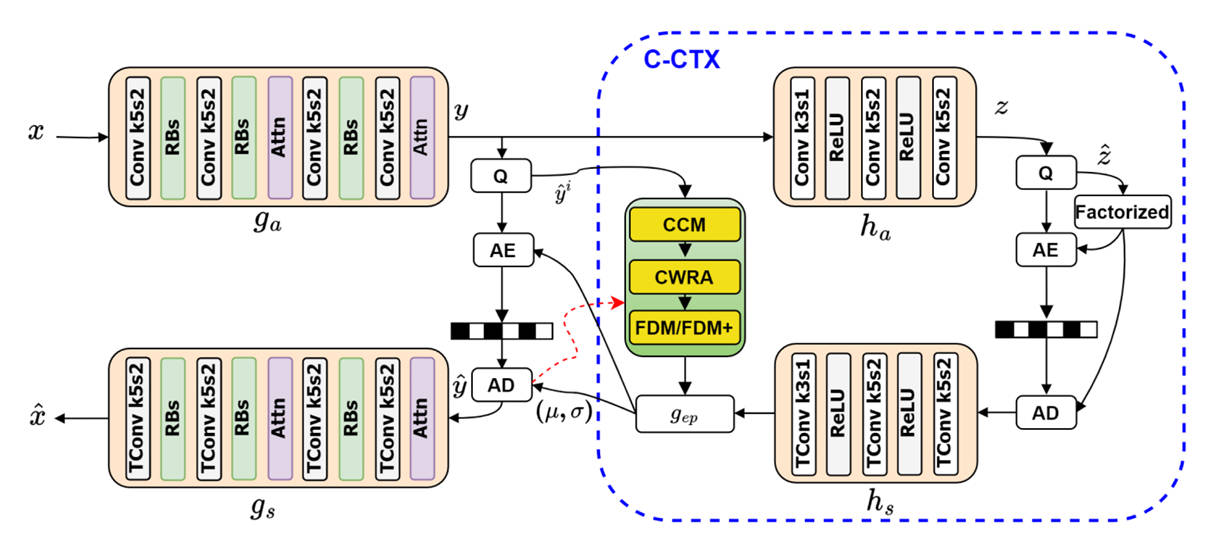
Representative figure for C-CTX: Cubic-Checkerboard Context Entropy Model for Learned Image Compression
C-CTX: Cubic-Checkerboard Context Entropy Model for Learned Image Compression

Shiyu Feng, Linwei Zhu, Yun Zhang, Na Li, Wenhui Wu, Shiqi Wang. IEEE Transactions on Multimedia, vol. 28, pp. 1756-1766, 2026.

Summary: C-CTX organizes latent context jointly across spatial and channel dimensions for learned image compression. Channel re-arrangement and multiple context prediction modes provide more accurate probability estimates and improve rate-distortion performance.

papercodeprojectdigest
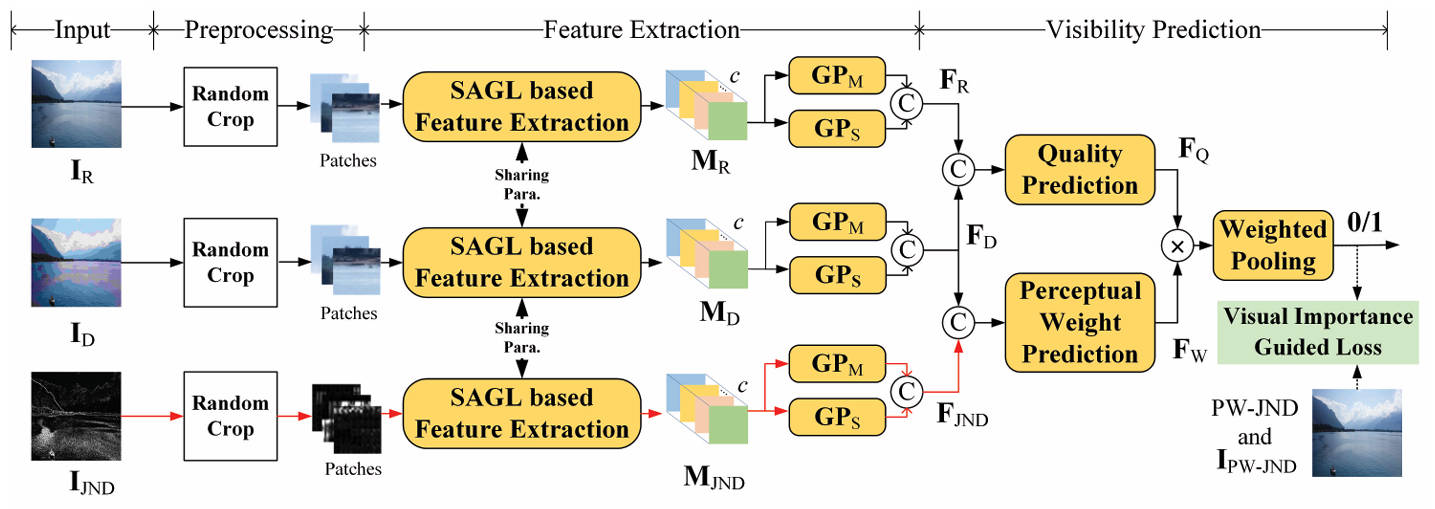
Representative figure for VP-JND: Visual Perception Assisted Deep Picture-Wise Just Noticeable Distortion Prediction Model for Image Compression
VP-JND: Visual Perception Assisted Deep Picture-Wise Just Noticeable Distortion Prediction Model for Image Compression

Yun Zhang, Shisheng Zhang, Na Li, Chunling Fan, Raouf Hamzaoui. IEEE Transactions on Circuits and Systems for Video Technology, vol. 36, no. 1, pp. 622-636, 2026.

Summary: VP-JND predicts the picture-wise distortion threshold that is just noticeable to human observers. The predicted threshold can guide coding parameters and bit allocation, reducing perceptual redundancy while maintaining visual quality.
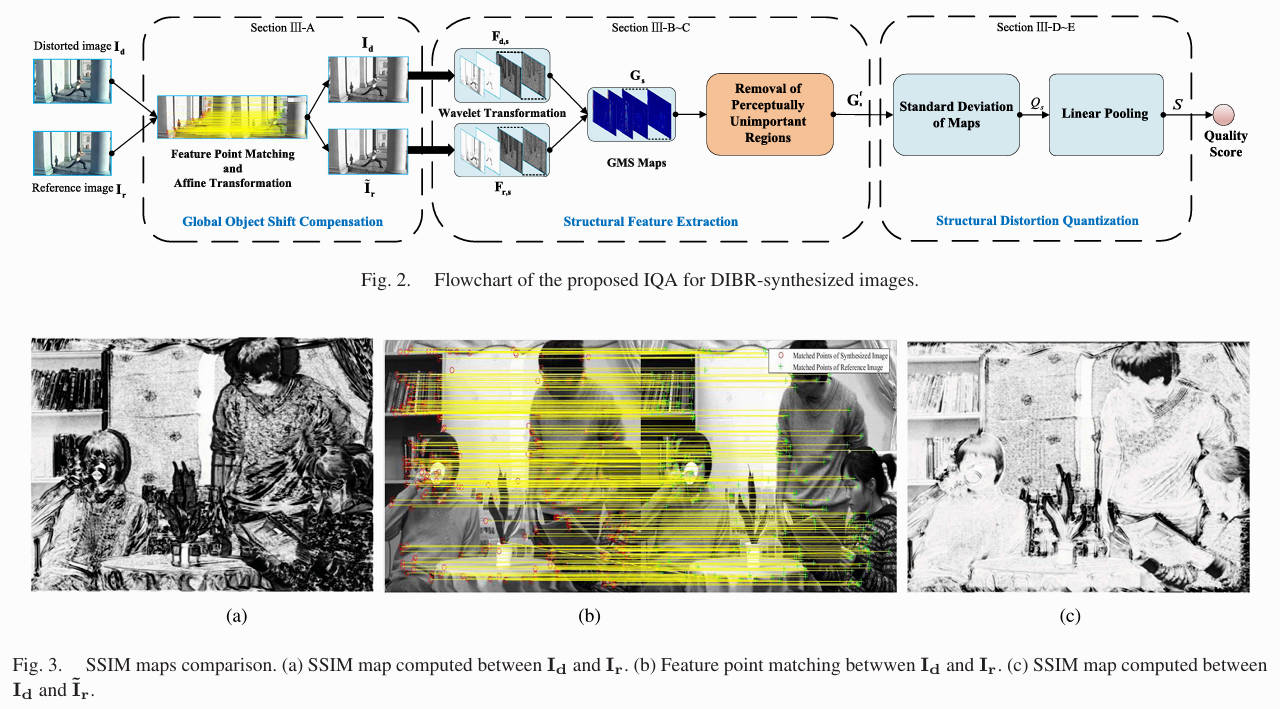
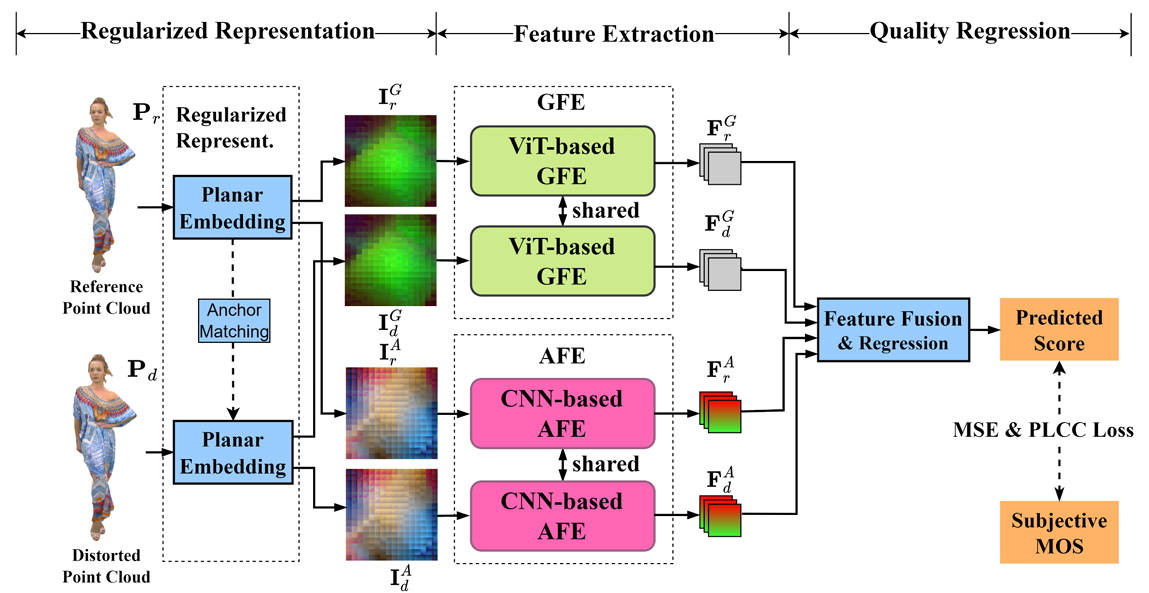
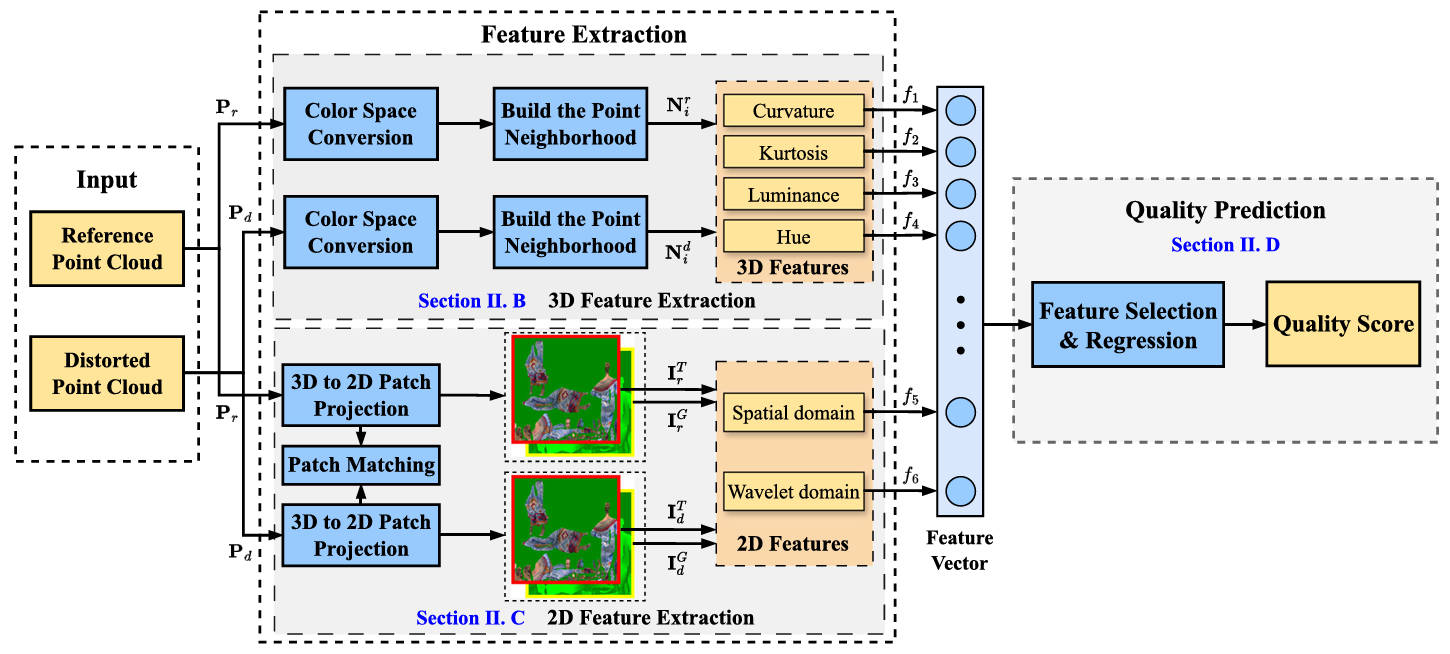
Representative figure for RegR-PCQA: Deep Learning based Colored Point Cloud Quality Assessment Using 3D-to-2D Regularized Representation
RegR-PCQA: Deep Learning based Colored Point Cloud Quality Assessment Using 3D-to-2D Regularized Representation

Yun Zhang, Cui Mao, Na Li, Chunling Fan, Weisi Lin. IEEE Transactions on Multimedia, vol. 28, pp. 1894-1908, 2026.

Summary: The method regularizes colored point clouds into 2D geometry and attribute maps before extracting complementary cues. ViT-based geometry modeling, CNN-based attribute modeling, and quality regression are combined for objective colored point cloud assessment.

papercodeprojectdigest
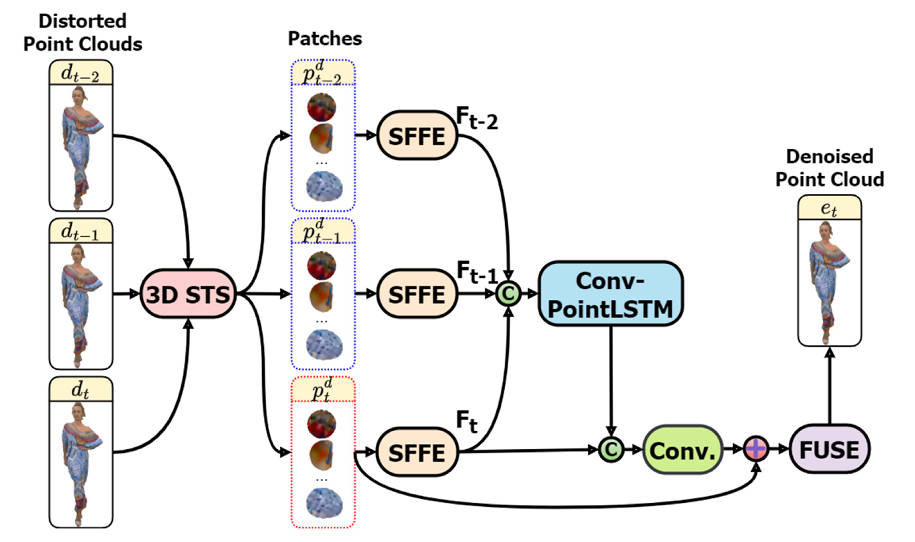
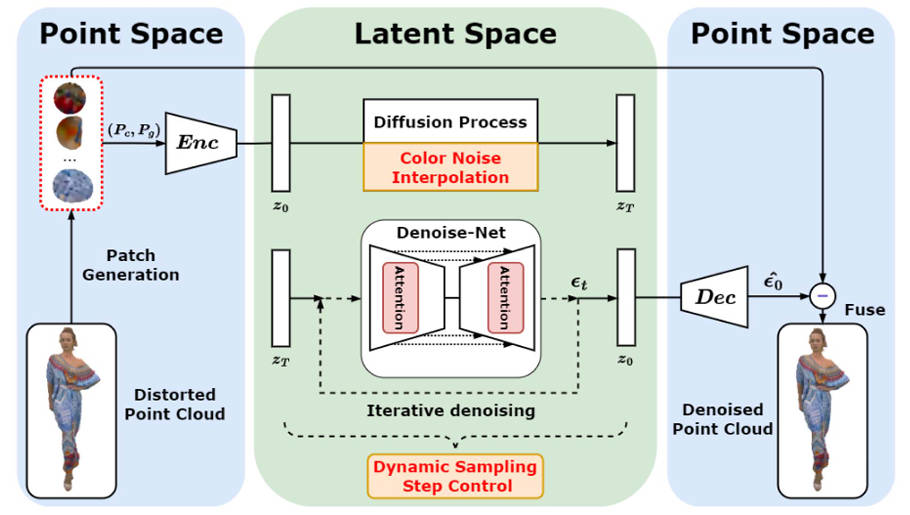
Representative figure for Temporal Consistency-Aware Dynamic Point Clouds Color Attribute Enhancement
Temporal Consistency-Aware Dynamic Point Clouds Color Attribute Enhancement

Linwei Zhu, Ruxu Liang, Yun Zhang, Hui Yuan, Sam Kwong. IEEE Transactions on Multimedia, 2026.

Summary: A 3D spatiotemporal search and temporal feature fusion pipeline addresses color noise and flicker in dynamic point clouds. Local feature extraction and Conv-PointLSTM exploit inter-frame consistency to recover more stable color attributes.

papercodeprojectdigest
180+SCI / EI

Papers

Research spans visual coding, perceptual quality, 3D vision, and intelligent media, including over 70 papers in IEEE/ACM Transactions.

1Monograph

Monograph

Three-Dimensional Video Signal Processing presents a systematic account of 3D video representation, coding, and processing.

50+Inventions

Patents

More than 50 granted Chinese, U.S., and PCT invention patents support the translation of research into practical technologies.